 Jeremy Neely
AI & Agents · Production
TokenX
Measures what each Hatz AI model really costs, then helps people choose.
Built for: AME staff and Secure AI clients choosing AI models
The problem
Hatz offers dozens of AI models but does not publish a per-model credit rate, and credits post in delayed batches. Without real numbers, people overspend or pick a cheap model that fails at the job.
What I built
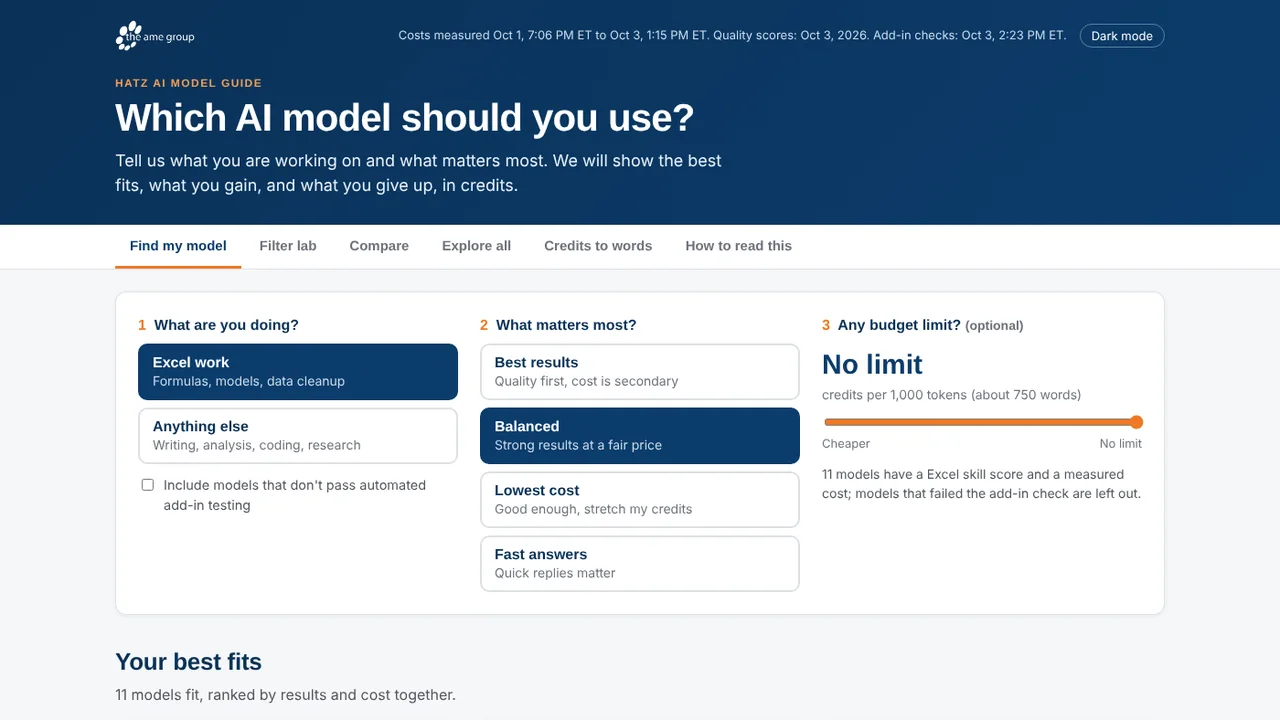
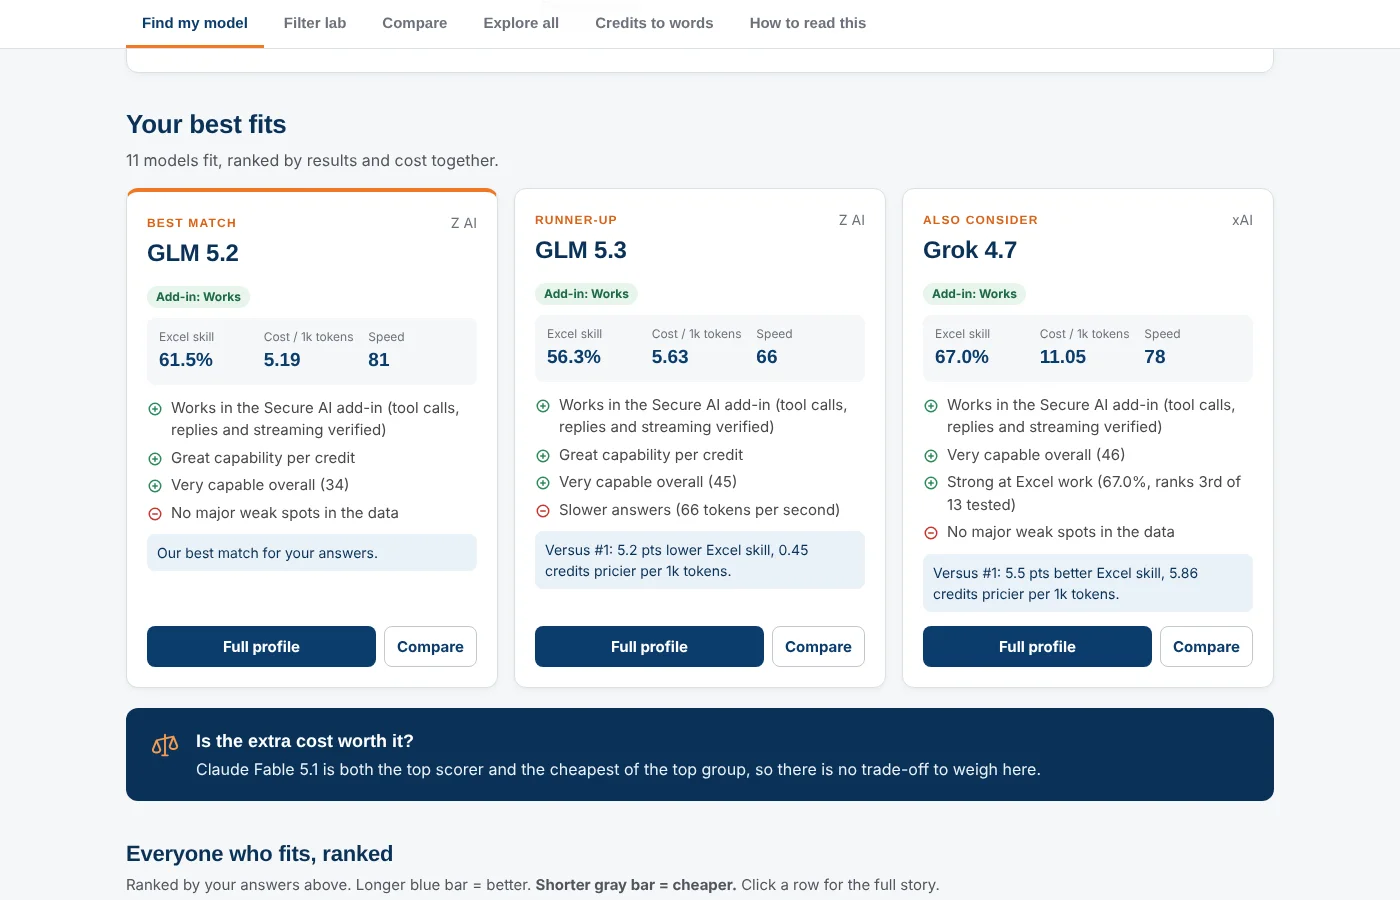
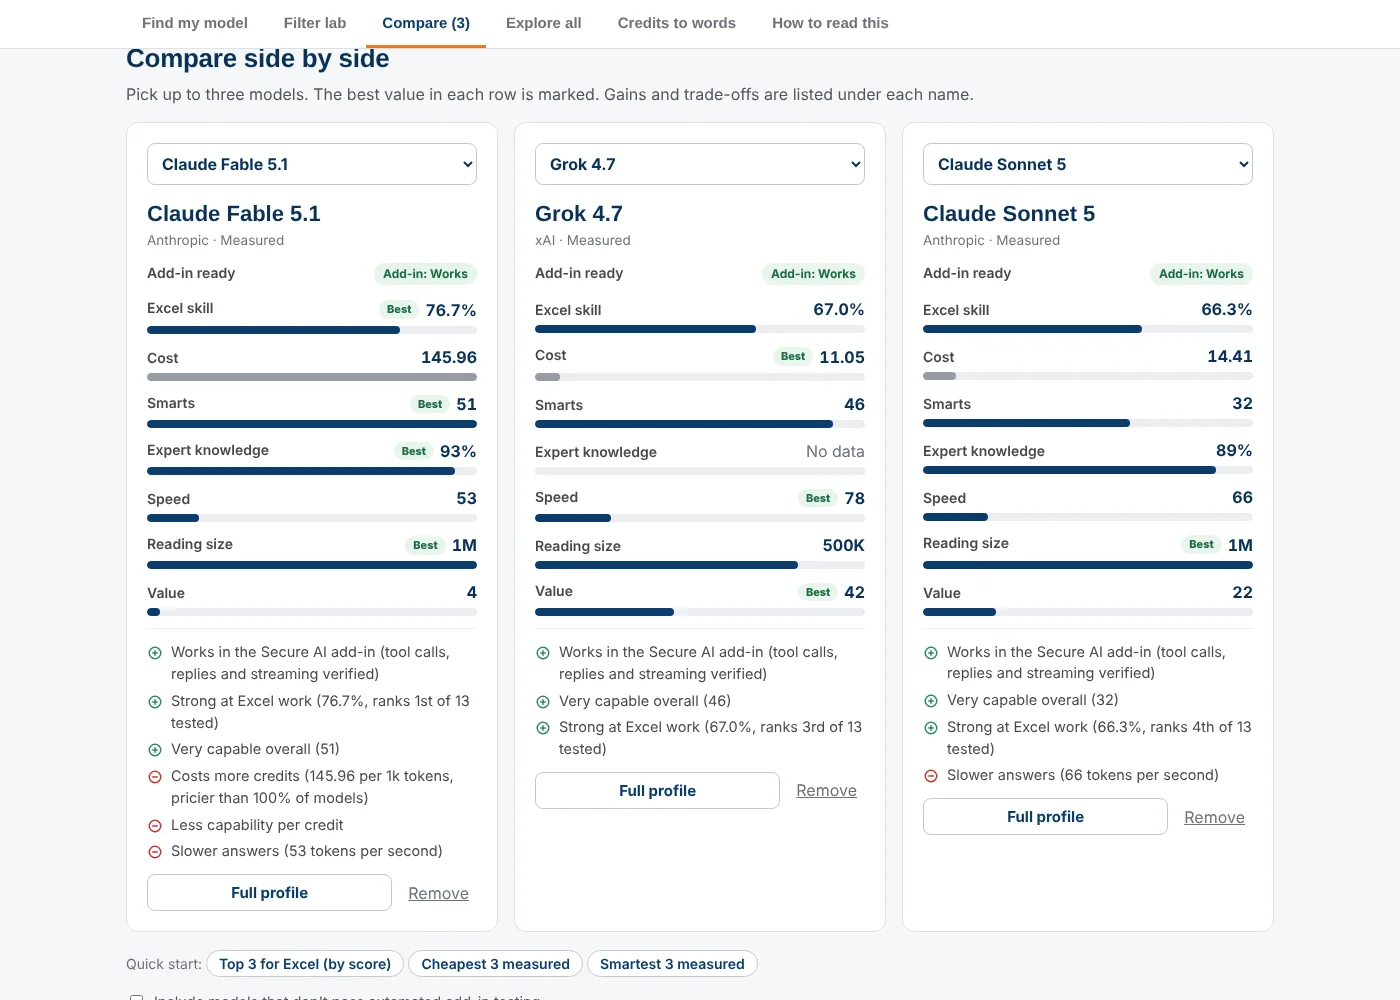
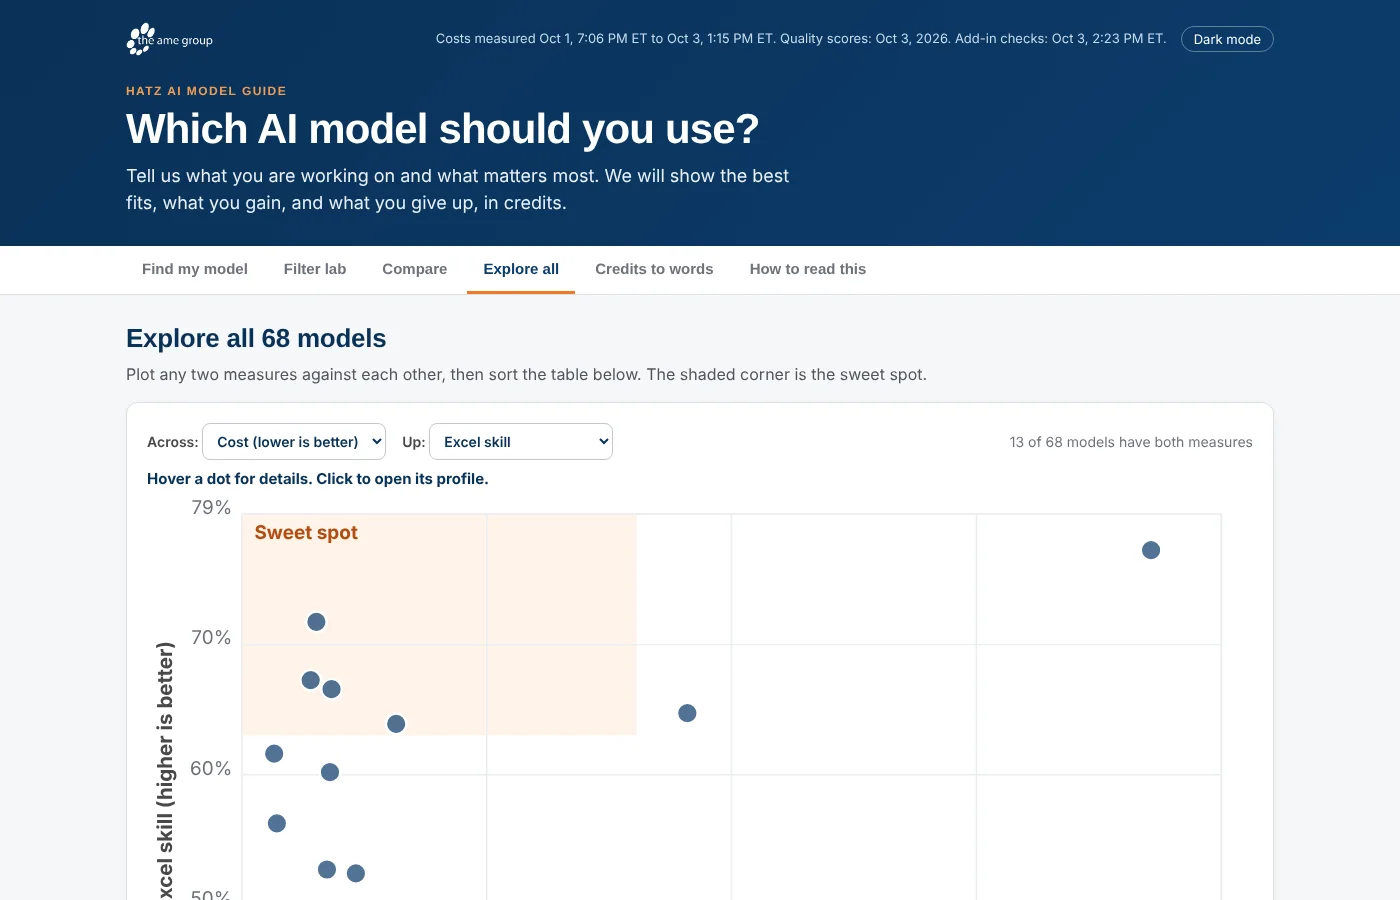
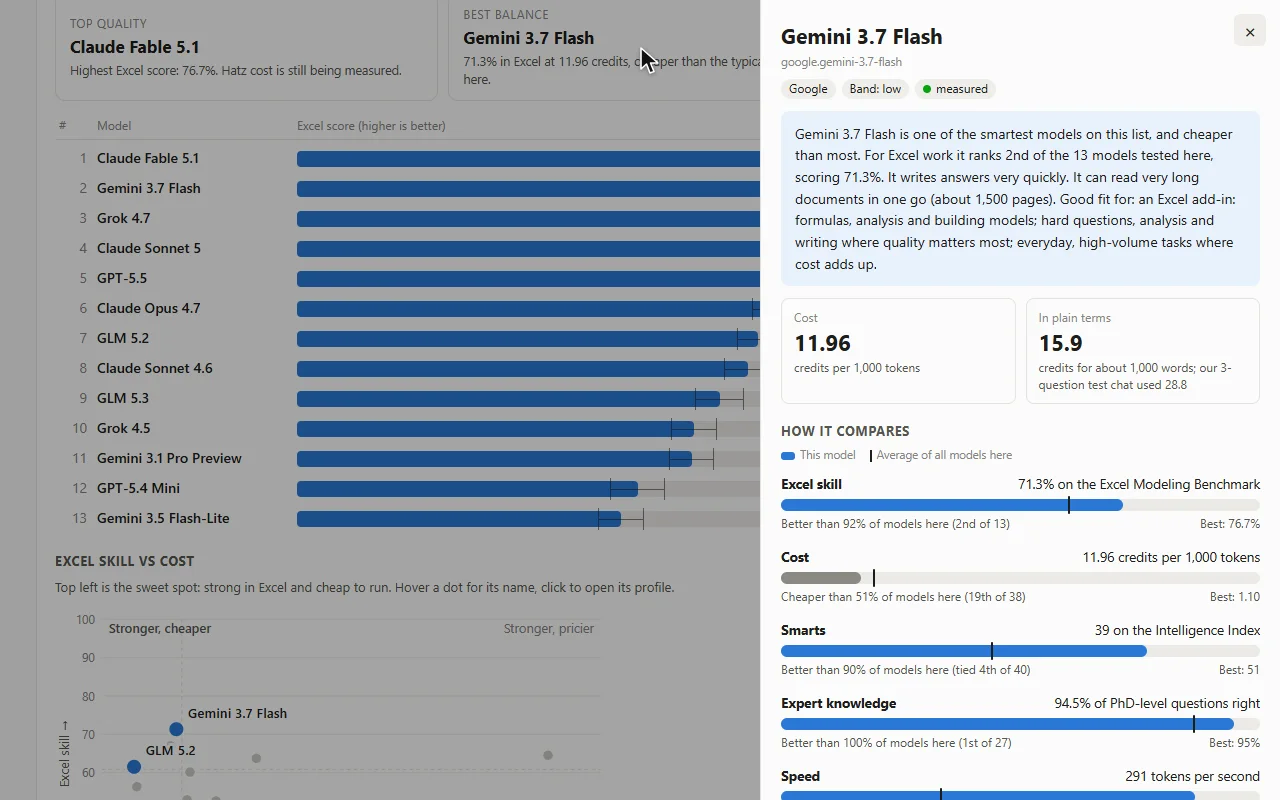
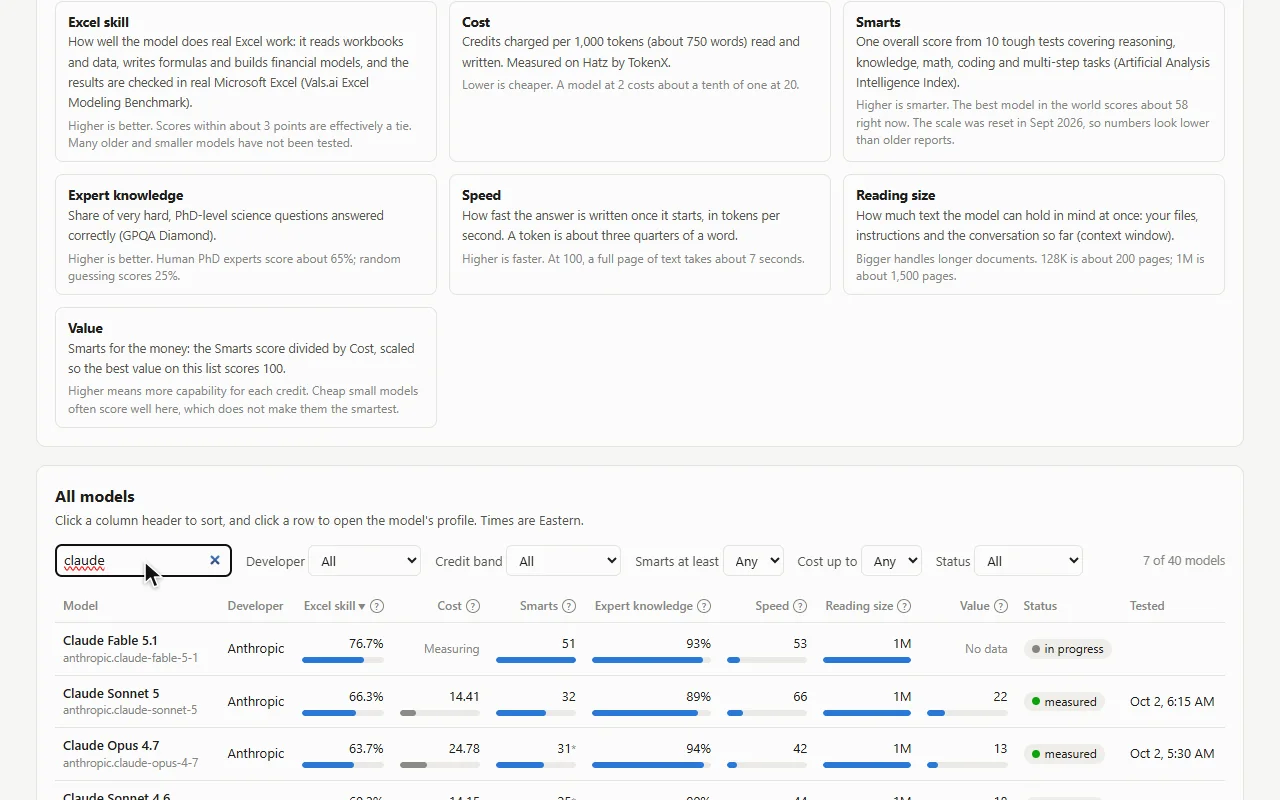
I built a Python command-line tool that runs the same chat on every Hatz model and watches the credit meter to measure cost per 1,000 tokens. The results feed a plain-language HTML model guide that also ships inside Secure AI for Excel.
How it works
- Take a baseline reading of the credit meter.
- Run a fixed sample chat on one model.
- Wait for the credits to post and compute the rate.
- Retest suspect results and save progress safely.
- Merge costs with public benchmarks into the HTML guide.
Built with
- Python 3.10+ (stdlib only)
- unittest
- Windows DPAPI
- Hatz AI REST API
- Node.js
- HTML/CSS/JavaScript
More screens
More of Jeremy's work
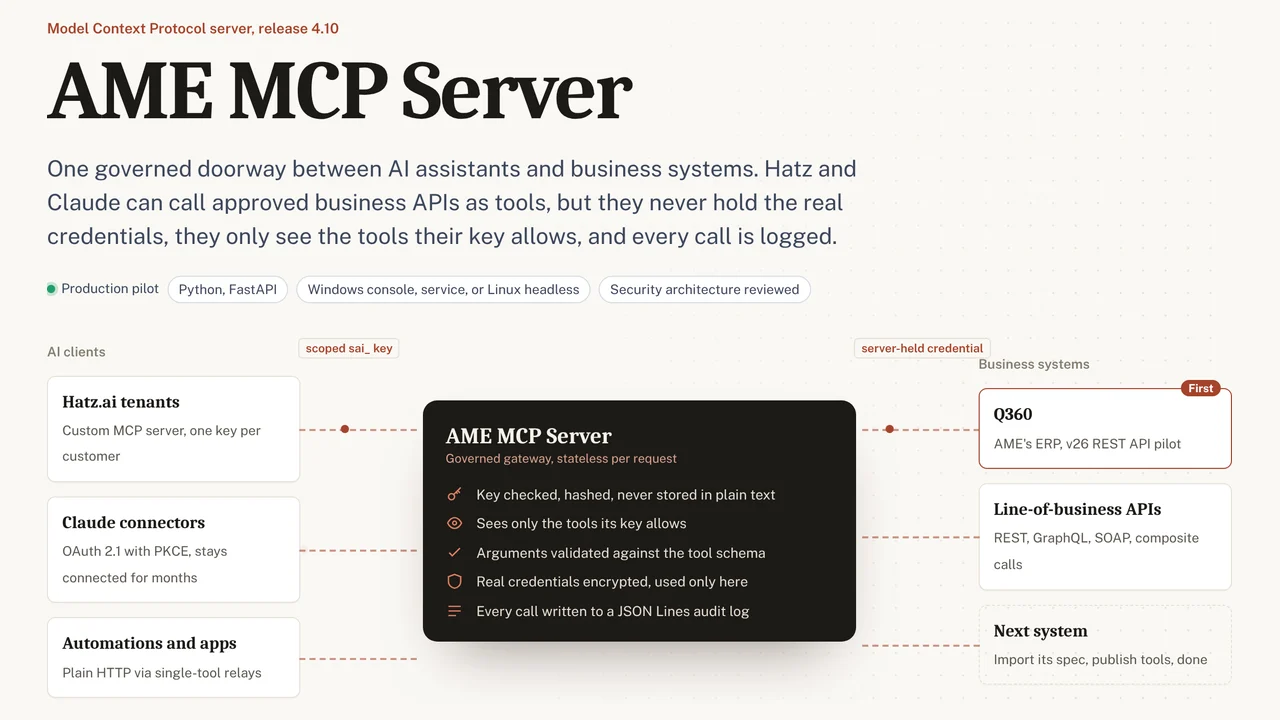 AME MCP ServerOne governed doorway between AI assistants and business systems.
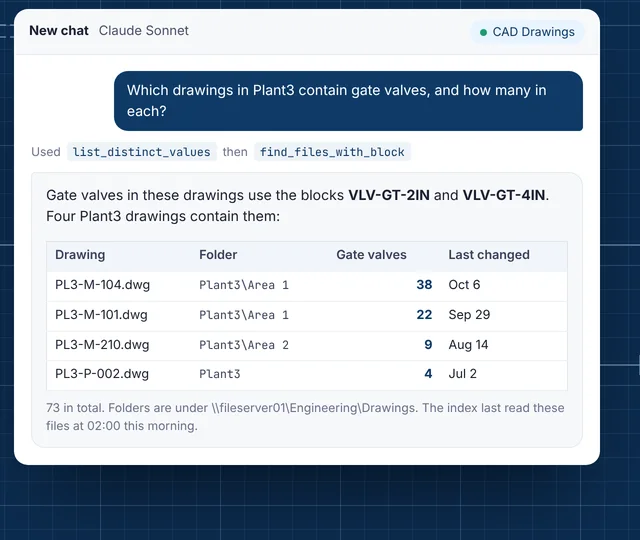 CAD Drawing IndexLets staff ask their AI assistant what is inside AutoCAD drawings.
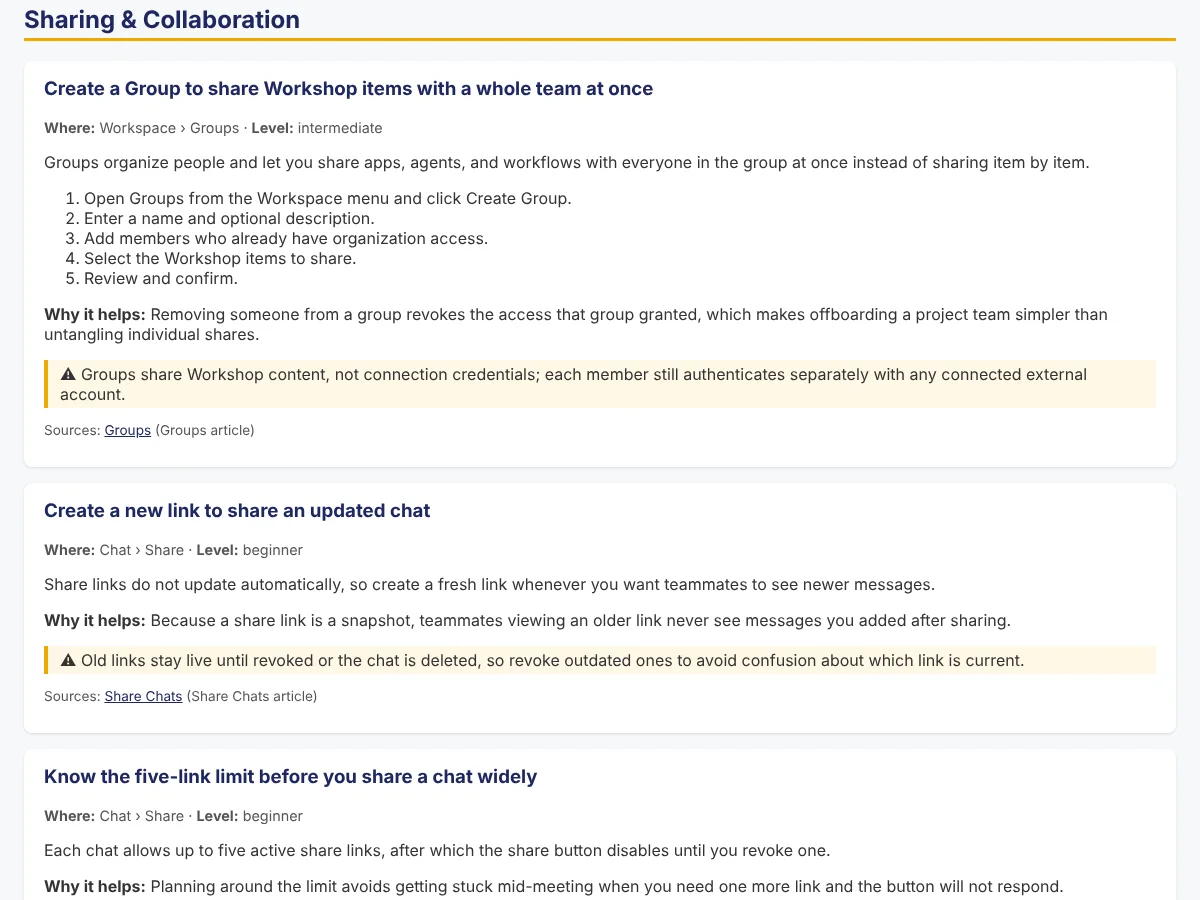 Secure AI Hatz TipsFact-checked how-to answers inside the AI chat customers already use.
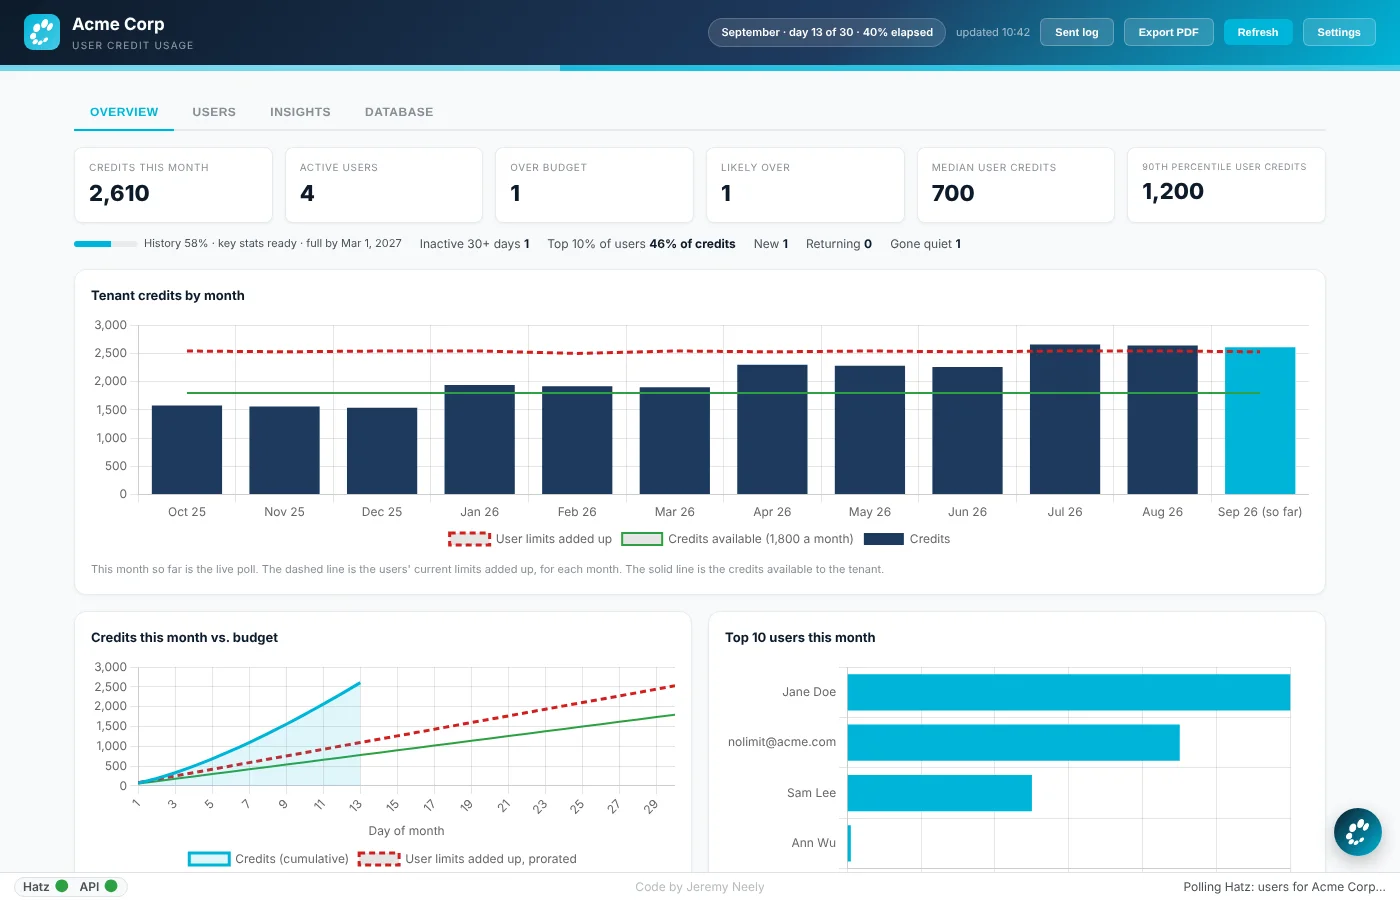 Hatz User WatchWarns admins before any person runs out of AI credits.
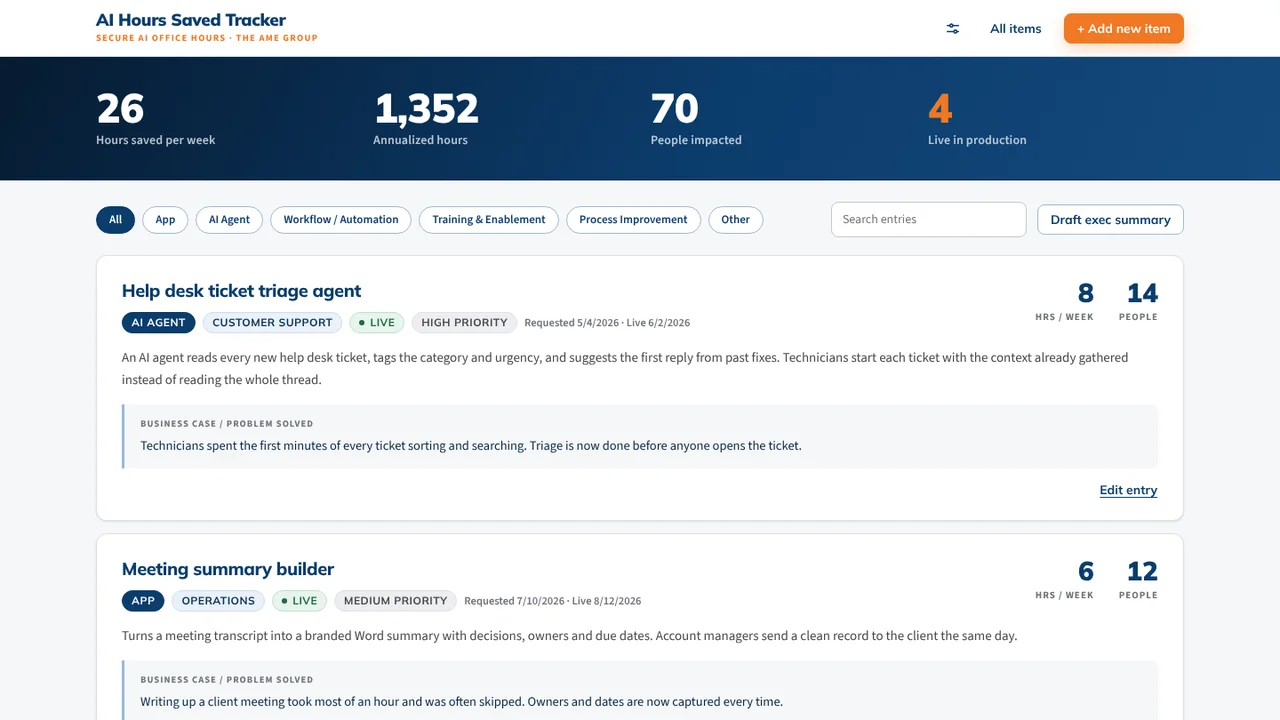 AI Hours TrackerAI interviews staff and writes up each AI time-saving win for leadership.
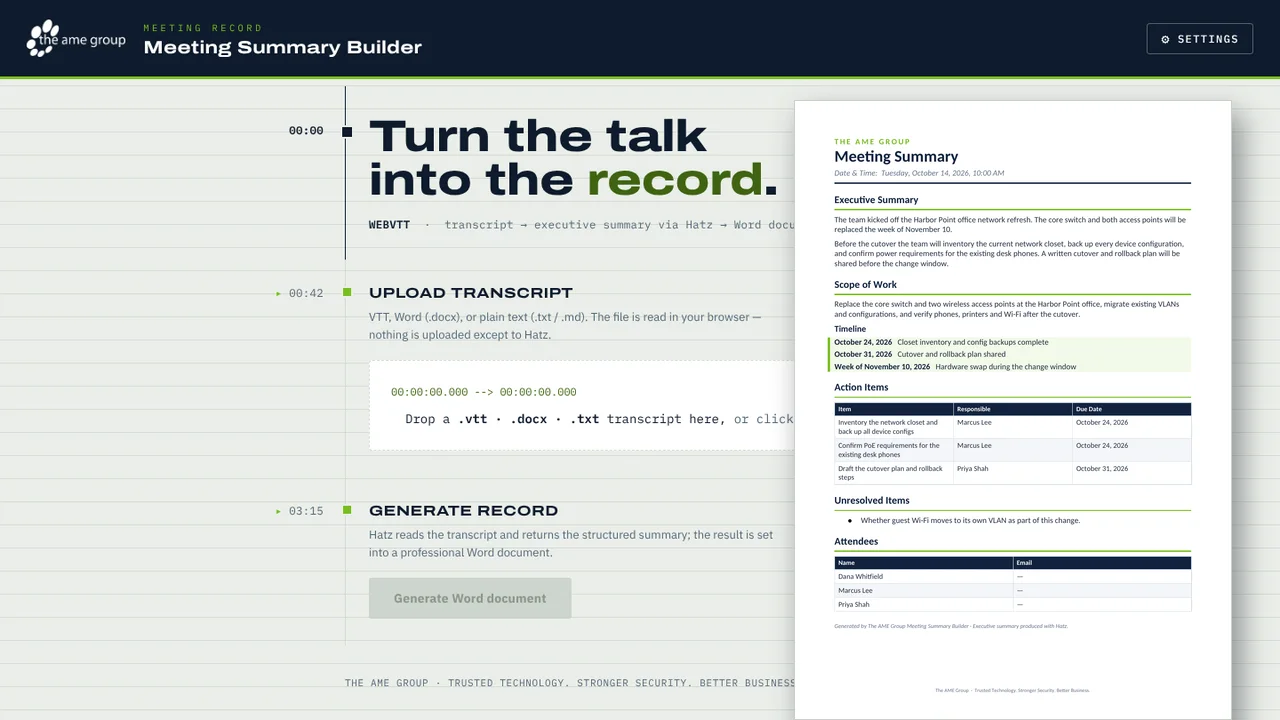 Meeting Summary BuilderTurns a Teams or Zoom transcript into a branded Word meeting summary.